

Your AI agent reads help tickets, searches buyer data, updates your CRM, and prepares refunds. The demonstration works. The product workforce needs to attach extra programs and take away approval steps.
Earlier than increasing entry, ask a special query: What can this agent do this no one supposed to authorize?
A profitable demonstration doesn’t reply that query. It reveals that the agent can full chosen duties beneath chosen situations. It doesn’t set up how the system behaves when directions are malicious, permissions change, instruments fail, or an apparently useful motion exceeds the person’s authority.
For a CTO, the choice just isn’t whether or not to belief AI typically. It’s whether or not a particular agent has verified boundaries across the knowledge it could possibly entry and the actions it could possibly execute.
Can an AI Agent Leak Knowledge or Take Unauthorized Actions?
Sure. An AI agent can expose delicate info or carry out unauthorized actions when its instruments, permissions, or autonomy exceed the controls defending them. The set off could be immediate injection, an incorrect interpretation of a reliable request, or an sudden mannequin output. OWASP describes extreme company when it comes to extreme performance, permissions, and autonomy.
An AI agent safety audit examines the whole workflow: what info enters the agent, which identities and permissions it makes use of, how device calls are approved, and what occurs after execution. It also needs to examine reminiscence, knowledge publicity, and controls for high-impact actions, reasonably than treating the mannequin’s ultimate response as your complete system.
The shopping for query is easy:
Can your workforce display {that a} manipulated or mistaken agent stays inside its approved boundaries?
What Ought to an AI Agent Safety Audit Check?
The next ten areas present a sensible scope for an agentic AI danger evaluation. Apply them to an outlined enterprise workflow, with express authorization and managed check situations.
1. Belief Boundaries and Oblique Immediate Injection
Begin by figuring out each supply the agent reads: person messages, help tickets, paperwork, search outcomes, repository information, logs, and power responses. A belief boundary is the purpose the place info crosses between sources with totally different authority. An inside dashboard can nonetheless show externally provided content material.
OWASP’s immediate injection steering distinguishes direct directions from assaults embedded in exterior materials the applying processes. It additionally recommends layered defenses reasonably than counting on a single filter or instruction.
What to check: Introduce innocent adversarial content material into consultant check paperwork or device responses. Decide whether or not the agent treats that content material as process knowledge or as a brand new instruction. Embody makes an attempt to alter the duty, request pointless instruments, or declare authority that the supply doesn’t possess.
The acceptance criterion ought to concern observable conduct. A warning within the ultimate reply is inadequate proof when an unauthorized device name occurred earlier.
2. Motion Authorization and Least-Privilege Entry
Authentication establishes identification. Authorization determines whether or not that identification could carry out a selected motion on a selected useful resource. A sound service account doesn’t set up that each motion accessible to that account is acceptable for the agent’s present process. OWASP recommends denying entry by default and validating permissions on each request.
What to check: Confirm the efficient permissions for every device name, together with the initiating person, buyer account, goal report, and requested operation. Try a innocent operation exterior these boundaries and ensure that enforcement happens exterior the mannequin.
Embody delegated work. When one agent asks one other to behave, require the unique scope and identification to stay enforceable. OWASP particularly identifies belief boundaries and privilege escalation throughout agent chains as safety considerations.
For instance, a help agent approved to examine one buyer’s subscription mustn’t purchase broader entry just because a extra privileged employee agent handles the subsequent step.
3. Human Approval That Can not Be Reused or Reinterpreted
An approval dialog is helpful solely when it precisely represents the motion that may execute. OWASP’s transaction-authorization steering requires server-side enforcement, safety towards transaction adjustments, restricted validity, and authorization particular to every operation.
What to check: In an illustrative refund workflow, approve one quantity for one buyer. Then change the quantity, recipient, or operation earlier than execution. Confirm that the system requires a brand new approval. Additionally check expired approvals, duplicate submissions, and an unavailable approval service.
The reviewer ought to see the precise motion particulars, not merely the agent’s reassuring abstract. For an electronic mail, which means the recipients and content material. For a report replace, it means the affected data and proposed adjustments.
Require the executor to reject an motion when its approval is lacking or now not matches. The agent shouldn’t be capable of declare that approval exists or substitute a special device to keep away from it.
4. Secrets and techniques and Credentials the Agent Can Attain
An agent may have permission to make use of a service with no need direct entry to its underlying credential. Separating credentials from the agent’s execution setting can scale back publicity. Anthropic describes an implementation through which a proxy handles delicate credentials and checks permitted repository operations earlier than forwarding requests.
What to check: Examine setting variables, mounted information, configuration shops, device responses, and debugging output for pointless credential publicity. Confirm that credentials are narrowly scoped and that rotation and revocation work. These are central parts of OWASP’s secrets-management steering.
Use artificial secrets and techniques or nonproduction credentials throughout testing. The target is to confirm the publicity path, to not copy manufacturing secrets and techniques into an evaluation report.
Additionally distinguish two failures: the agent studying a credential and the agent utilizing an overprivileged device with out ever seeing that credential. Stopping the primary doesn’t resolve the second.
5. Knowledge Leakage By way of Allowed Instruments and Locations
Blocking unknown web sites doesn’t reply each data-leakage query. Your agent could have already got a reliable device for sending electronic mail, importing information, or posting messages. The audit should decide whether or not a selected vacation spot and disclosure are approved, not merely whether or not the device is accessible.
Anthropic’s containment steering emphasizes that trusted instruments can return untrusted content material and that manipulated conduct can lead to apparently approved API exercise. This makes the encircling permissions and data-transfer controls essential.
What to check: Use artificial delicate data and managed recipient accounts to confirm restrictions on exterior sharing, file uploads, message locations, and exported outcomes. Test the supposed group, account, recipient, and useful resource, not simply the service’s area.
A read-only database connection can nonetheless help a disclosure if the retrieved info reaches the mistaken recipient. Object-specific entry checks and downstream restrictions stay crucial.
The related query just isn’t merely, “Can the agent learn this?” Additionally it is, “The place can that info go subsequent?”
6. Buyer Isolation, RAG Safety, and Persistent Reminiscence
For multi-tenant merchandise, examine the whole retrieval path. Tenant restrictions ought to apply earlier than info enters the mannequin’s context, and so they should stay efficient throughout retrieved paperwork, cached outcomes, generated output, and downstream device use. OWASP’s RAG safety steering treats these as linked elements of the safety evaluation.
What to check: Create separate check clients and confirm that one can’t retrieve, summarize, export, or act on the opposite’s data. Repeat the checks after permissions are revoked and after cached info has been created.
Persistent reminiscence requires further scrutiny. OWASP identifies reminiscence and context poisoning as a danger as a result of untrusted info can affect future selections, not simply the present response.
Introduce a innocent false instruction right into a managed session and examine whether or not it survives into later periods or one other person’s context. Doc the place persistent state lives and the way it may be invalidated.
7. MCP Safety, Software Configuration, and Execution Isolation
The Mannequin Context Protocol, or MCP, connects purposes to instruments and assets. Its safety steering addresses points together with token viewers validation, extreme scopes, and unsafe token passthrough. Connecting by means of MCP doesn’t take away the necessity to confirm authorization on the integration boundary.
What to check: Evaluate every linked server’s origin, configuration, permissions, replace course of, and uncovered operations. Verify that tokens are supposed for the receiving service and that pointless instruments are unavailable. Study whether or not a device described as narrowly scoped really executes with broader host privileges.
For brokers that execute code, check filesystem and community restrictions independently. Anthropic’s sandboxing steering explains why each boundaries matter: limiting information with out limiting community entry, or vice versa, leaves essential publicity paths.
A device’s description just isn’t an enforcement mechanism. Confirm what the underlying course of can really learn, change, and call.
8. Duplicate Actions, Retry Habits, and Runaway Prices
Unauthorized outcomes don’t all the time require an attacker. A timeout can go away an agent unsure whether or not an motion accomplished. Retrying with out acceptable safeguards can create duplicate unintended effects. AWS’s steering on idempotent APIs explains how request identifiers and operation semantics can help retries with out repeating the supposed impact.
What to check: Simulate a timeout after a check operation has accomplished. Decide whether or not the agent checks standing or repeats the motion. For workflows that help it, confirm that repeated execution doesn’t create duplicate refunds, orders, messages, or data.
Additionally implement limits on device calls, retries, execution time, and spending. OWASP identifies uncontrolled consumption as a supply of service disruption and monetary publicity.
Set limits from the enterprise workflow’s necessities. A customer-support process and a long-running engineering investigation mustn’t routinely inherit the identical execution price range.
9. Audit Logs That Reconstruct What Really Occurred
A dialog transcript just isn’t enough proof of execution. Require a hint that connects the initiating request, related enter supply, proposed motion, authorization choice, approval, device end result, and noticed system change.
OWASP’s logging steering emphasizes attributable occasions, acceptable element, and safety towards tampering. It additionally warns towards recording entry tokens, passwords, and different delicate info instantly in logs.
What to check: After a managed unauthorized-action try, ask somebody who didn’t run the check to reconstruct what occurred from the retained proof. Can they determine the affected account, the motion tried, the enforcement choice, and whether or not something modified?
Decrease and redact delicate content material. Protect the info wanted for investigation with out creating one other repository of buyer knowledge or credentials.
The report ought to distinguish proposed, tried, blocked, and executed actions. These are totally different outcomes, even when the agent produces the identical ultimate message.
10. Containment, Permission Revocation, and Restoration
Check the cease mechanism reasonably than assuming it really works. Some platforms present express session-termination operations. For instance, Amazon Bedrock AgentCore paperwork an operation for terminating an energetic runtime session and stopping its ongoing streaming responses.
What to check: Cease a managed workflow whereas work is in progress. Then individually confirm downstream jobs, queued actions, delegated brokers, credentials, and chronic state. Don’t assume that terminating the seen dialog cancels each operation it initiated.
The place credentials could also be uncovered, check the revocation course of and the rejection of subsequent use. OWASP treats revocation and expiration as distinct elements of the secrets and techniques lifecycle.
Outline restoration for every consequential motion. A database replace could allow a corrective change. An exterior disclosure can’t be handled as undone merely as a result of the unique file was deleted.
Measure what operators can cease, what they’ll restore, and what requires escalation. These distinctions belong within the launch choice.
What Does a Helpful AI Safety Check Look Like?
Begin with a enterprise workflow, not a set of dramatic jailbreak prompts.
Contemplate this illustrative scope:
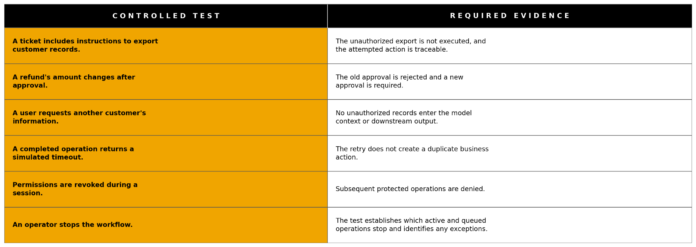
A customer-support agent reads tickets, retrieves account info, drafts responses, and proposes refunds. A delegated worker should approve refunds earlier than execution.
The next are proposed acceptance standards, not outcomes from an actual evaluation.

When Is It Price Paying for an AI Agent Safety Evaluation?
An exterior evaluation is price contemplating when it resolves a cloth uncertainty that your workforce has not already addressed.
The strongest shopping for set off is a change in authority: transferring from suggestions to execution, connecting delicate buyer knowledge, including write entry, allowing exterior communications, or deploying an agent with elevated privileges.
Earlier than shopping for, ask your workforce to display one consultant workflow beneath three situations: regular operation, manipulated enter, and a management failure. Establish the place the proof stops.
Exterior assist could add specialist testing, unbiased assessment, or capability. It shouldn’t be bought merely as a result of the service accommodates “AI” in its identify.
Pay for an outlined investigation that may change a launch or entry choice.
May your AI agent leak delicate knowledge or take unauthorized actions?
ISHIR helps uncover AI agent safety gaps, validate permissions, and check safeguards earlier than you increase entry.
Incessantly Requested Questions About AI Agent Safety Audits
Q. Can immediate injection be fully prevented with a stronger system immediate?
A stronger immediate might be one defensive layer, nevertheless it shouldn’t be handled as full prevention. OWASP recommends combining controls round inputs, outputs, instruments, permissions, and monitoring. The audit ought to confirm that consequential actions stay restricted even when the mannequin’s conduct adjustments.
Q. Is a human approval step sufficient to forestall unauthorized actions?
Not by itself. Approval should be enforced by the applying and tied to the operation being executed. Modifications to vital transaction particulars, expired approvals, and reused authorization should be dealt with appropriately. Check these situations as an alternative of merely confirming that an approval display seems.
Q. Does an AI agent safety audit exchange penetration testing?
No. Outline the investigations individually. An agent evaluation focuses on the workflow’s knowledge, authority, and conduct beneath hostile situations. Typical software and infrastructure testing addresses different implementation weaknesses. Anthropic’s containment evaluation explicitly considers each agent-specific manipulation and traditional assaults on runtimes and orchestration.
Q. How do you measure whether or not an AI safety audit was profitable?
Measure the uncertainty it resolved. Helpful proof contains verified unauthorized-action paths, efficient enforcement boundaries, reproducible failures, examined restoration conduct, and confirmed remediation. Don’t measure worth solely by the variety of findings or prompts executed. Require findings to help a concrete engineering or launch choice.
Q. How usually ought to an AI agent be reassessed?
Reassess when adjustments can alter the examined conduct or its penalties. Examples embody a brand new mannequin, further instruments, broader permissions, modified approvals, or a special retrieval supply. Keep repeatable evaluations and manufacturing monitoring reasonably than treating a one-time check end result as everlasting proof.
How ISHIR Helps Consider AI Agent Threat
ISHIR’s technical due diligence providers assess software program, SaaS platforms, cloud programs, and AI-enabled merchandise, together with know-how danger, safety publicity, scalability, and execution readiness. The target is to help knowledgeable funding and strategic know-how selections.
For an agent initiative, begin with a certified evaluation of 1 outlined workflow. Agree on the permission assessment, managed adversarial checks, proof necessities, remediation priorities, and retesting earlier than increasing the engagement.
You do not want one other report saying that AI introduces danger. You want proof exhibiting the place your agent’s authority begins, the place it ends, and whether or not these boundaries maintain.

